Most review sites that lean on AI for every stage of production end up with the same problem: the reviews sound fine, rank for a week or two, and then disappear from search results as Google’s systems catch up. The pattern is consistent enough now that it’s worth understanding before you build a publishing schedule around it. AI can genuinely speed up a review site. It cannot replace the parts of a review that make a reader trust it, and it cannot replace the parts that make a search engine trust it either.
This article lays out exactly how to use AI for affiliate product reviews: a specific pipeline where AI does the heavy lifting, where a human has to step in, and how to batch the whole thing so you publish more reviews per month without publishing thin ones.
Why AI generated reviews get buried in search results
Search engines have gotten better at spotting a review that was never touched by someone who used the product. The tells are consistent: vague praise that could apply to any item in the category, a list of specs copied from the manufacturer’s page, no photos or screenshots that aren’t stock images, and a drawbacks section that reads like it was added to satisfy a template rather than because the writer hit a real limitation.
None of that is about AI detection in the sense of a tool flagging robotic phrasing. It’s about a content quality system that was built around a simple idea: people searching for a product review want to know what happens when someone actually uses the thing. A review that could have been written by someone who has never touched the product fails that test regardless of which tool wrote it.
The volume temptation is real. AI lets you draft a review in minutes instead of hours, so the obvious move is to draft forty reviews a month instead of eight. But a site full of forty generic reviews ranks worse, on average, than a site with eight specific ones, because the ranking signal isn’t word count or publishing frequency. It’s whether the page answers the question a buyer actually has.
The quality floor AI can never cross on its own
There’s a line that separates what AI can produce from what a review needs, and it doesn’t move no matter how good the model gets, because the line isn’t about writing quality. It’s about access to information the model doesn’t have.
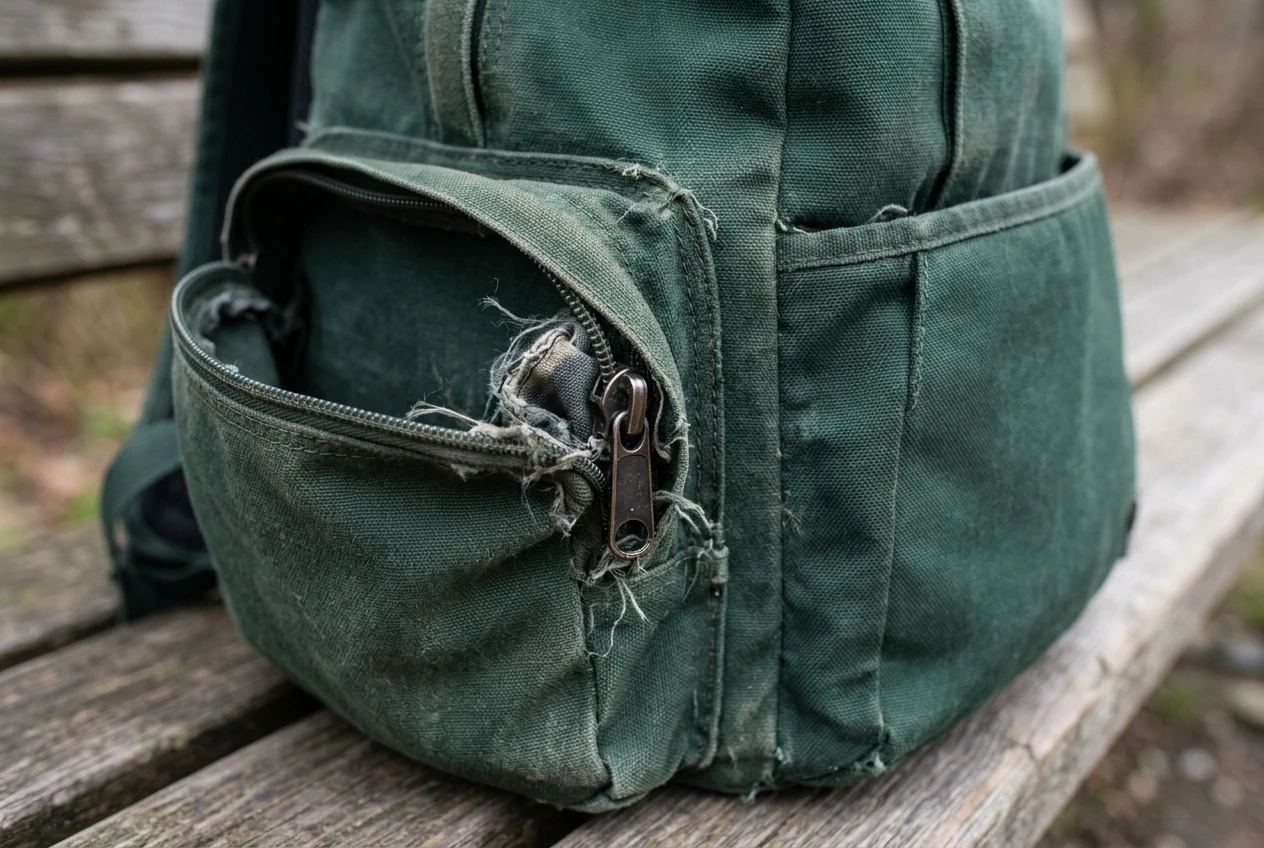
AI cannot have used the product. It can’t tell you the battery dropped to 40% after three hours of screen-on time, because it was never in the room when that happened. It can’t tell you the zipper on the left pocket catches on the lining, because it doesn’t have a left pocket. Any number, measurement, or specific failure point in a review has to come from somewhere real: your own use of the product, a verified source, user forums where real buyers report the same issue repeatedly, or documentation you’ve checked against the actual item.
The same floor applies to drawbacks. A generic review lists a drawback that sounds like a drawback but costs the manufacturer nothing: “it’s a bit pricier than some alternatives,” “the learning curve takes a little getting used to.” A real review names a drawback that actually costs the reader something if they don’t know about it going in. That specificity is what both readers and ranking systems are picking up on, and it’s the one thing a model working from training data and a product page cannot invent on its own.
A repeatable pipeline: research, draft, fact check, edit, publish
Treat the review as five separate stages rather than one prompt. Each stage has a different job, and collapsing them into one is where quality slips.
Research. Before any draft exists, gather what’s actually knowable about the product: official specs, pricing, what’s in the box, what the manufacturer claims, and what real users say in reviews, forums, and comment sections. This stage is where you also note what you personally know or have access to, so the draft stage has real material to work with instead of a blank page.
Draft. This is where AI earns its place. Feed it the research, not a bare product name, and have it build structure: a working outline, a first pass at sections, a draft of the comparison table if the review includes one. The draft is a skeleton, not a finished piece.

Fact check. Every number, claim, and spec in the draft gets checked against a source before it goes further. Prices change, specs get revised between model years, and AI will occasionally state something with total confidence that is simply wrong. This stage is non-negotiable and it’s covered in more detail below.
Edit. A human rewrites the generic parts: the praise that could apply to anything, the drawbacks that don’t cost the reader anything, the voice that sounds like nobody in particular. This is also where first-hand detail gets added if you have it.
Publish. Final formatting, affiliate link placement, and a last read-through for anything that sounds like it came from a template.
Running these as distinct stages, rather than asking one prompt to do all five, is what keeps the output from reading like every other AI-assisted review on the internet.
Prompts that force specificity instead of generic praise
The quality of what AI gives you at the draft stage depends entirely on what you ask for. A prompt like “write a review of [product]” will produce generic praise every time, because that’s the most statistically likely output for that input. Better prompts constrain the model toward specificity:
-
“List five claims this manufacturer makes that are testable, and what evidence would confirm or contradict each one.”
-
“Based on this research, what are three drawbacks that would matter to a buyer who didn’t know about them in advance, not drawbacks that sound bad but don’t actually affect use?”
-
“Write this section without using any phrase that could apply to a different product in the same category. Flag anything you had to leave generic because the research didn’t cover it.”
-
“Compare this product to [competitor] on these three specific points only, using the numbers from the research provided, not general reputation.”
Notice the pattern: every prompt asks for something checkable, something tied to the research you fed in, or something that forces the model to admit a gap rather than paper over it with confident-sounding filler. The goal isn’t to make the AI sound more human. It’s to make the draft contain less of the vague material that needs removing later.
Where a human has to touch every single review before it goes live
There’s a short list of things that cannot go live without a human checking them, no matter how the draft was produced:
-
Every price, spec, and claim gets verified against a current source, not whatever the model generated. Prices and specs change; a confidently wrong number in a review damages trust the moment a reader notices.
-
Every drawback gets read by someone asking “does this actually cost the reader something, or does it just sound like a drawback.” If it’s the second one, it gets replaced.
-
Any first-hand detail the review claims gets checked against what you actually did. Never let a draft imply you tested something you didn’t. If you haven’t used the product, the review should be framed around research and verified user reports, not invented personal experience.
-
Affiliate disclosure and link placement get checked on every page, every time, not just the first few in a batch. For guidance on where links actually earn clicks without feeling forced, see the affiliate link placements readers actually click.
-
The opening and closing paragraphs, since these are the parts most likely to sound templated if nobody rewrites them, and the parts a reader uses to decide whether to trust the rest of the page.
This isn’t a formality step before publishing. It’s the stage where the review turns into something a specific person stands behind.
Building a batch schedule that scales output without scaling risk
The temptation with any pipeline is to run it at full speed the moment it works once. Resist that. Build the batch schedule around the slowest stage, which is almost always fact checking and editing, not drafting.
A workable rhythm for a solo operator: research and draft five to eight reviews in a block, since that stage benefits from momentum and similar products often share research sources. Then switch entirely to fact checking and editing mode for the same batch, treating it as a separate work session rather than finishing each review start to finish before moving to the next. Batching by stage, rather than by review, keeps you from rushing the verification step just because you want to move on to drafting the next one.

Cap the batch size to whatever you can realistically fact check and edit with full attention in the time you actually have. If that’s four reviews a week, publish four. A smaller number of reviews that pass the full pipeline will outperform a larger number where the verification stage got rushed on the last two to hit a deadline.
Leave room in the schedule for updates, too. A published review isn’t finished the day it goes live if the product gets a price change, a new version, or a wave of user complaints six months later. Revisiting older reviews on a schedule is part of the same batching logic, not a separate project.
Turning this into a checklist you actually follow every time
A pipeline only works if it survives contact with a Friday afternoon and a deadline. Write the stages down as a literal checklist and keep it where you draft:
-
Research gathered and sourced before drafting starts
-
Draft built from that research, not from a bare prompt
-
Every price, spec, and number checked against a current source
-
Every drawback tested against “does this cost the reader something”
-
First-hand claims checked against what was actually done
-
Generic praise rewritten in the edit pass
-
Affiliate links placed and disclosed correctly
-
Opening and closing paragraphs read for template language
Run every review against that list before it goes live, no exceptions for the ones you’re confident about. The confident ones are usually where a detail slips through.
This pipeline is one piece of a larger system. For the full workflow it slots into, from keyword research through to funnel tracking, see how to build a productive affiliate marketing workflow.